Kubeez · Audio · Gemini 3.8 Flash TTS
Gemini 3.8 Flash TTS
Two voices, a delivery for every line, 70 voices to cast
Gemini 3.8 Flash TTS turns a script into a conversation. Write one or two speakers as an ordered list of lines, give each line its own delivery style, and drop in any of 40 delivery tags like <laugh>, <sigh>, <whispers> or <short pause> that the model performs instead of reading aloud. Cast from 70 voices grouped by use case, let the language come straight from your text, and render up to 5,000 characters per generation as WAV. Billed from the same Kubeez wallet as music and video. Section images below are illustrative marketing stills; every clip in the sample band is real output.
Showcase
Real clips, straight from the model
Every clip below is real output from Gemini 3.8 Flash TTS, not a mock-up. Play the two-voice scene first, then audition voices from different use cases.
Two speakers, four lines
One generation with two voices, Alnilam and Laomedeia, a delivery style on each line, inline delivery tags and filler words switched on.
Script as written (the model adds the filler words)
- Alnilam: Okay, so we are live, and I have to ask. <short pause> Did you actually read the whole manual?
- Laomedeia: <laugh> Of course not. I read the first page, and then I just pressed every button until it worked.
- Alnilam: That is the most honest answer we have ever had on this show. <chuckle>
- Laomedeia: <sigh> And honestly? It worked on the third try. <whispers> Do not tell the engineers.
Voice previews
- FolaCall center
- ZephyrTutor
- KoreCommercial voiceover
- AlnilamPodcast
- EnzoStoryteller
- CharonCall center
- BodiTutor
- LumiTutor
A SCRIPT WITH STAGE DIRECTIONS
Write the lines, set the delivery on each one, and place tags exactly where the laugh, the breath or the pause belongs.

DELIVERY PER LINE
Every line carries its own delivery style, like 'tired night-shift radio host, slow and dry', so one speaker can change mood from line to line.

40 DELIVERY TAGS
Tags in angle brackets such as <laugh>, <sigh>, <gasp> and <long pause> are performed, not read aloud, so the line lands with real expression.

70 VOICES
Cast from 70 voices grouped by use case: tutor, commercial voiceover, podcast, storyteller, call center and more. The language is detected from your text.
Gemini 3.8 Flash TTS in the app and MCP
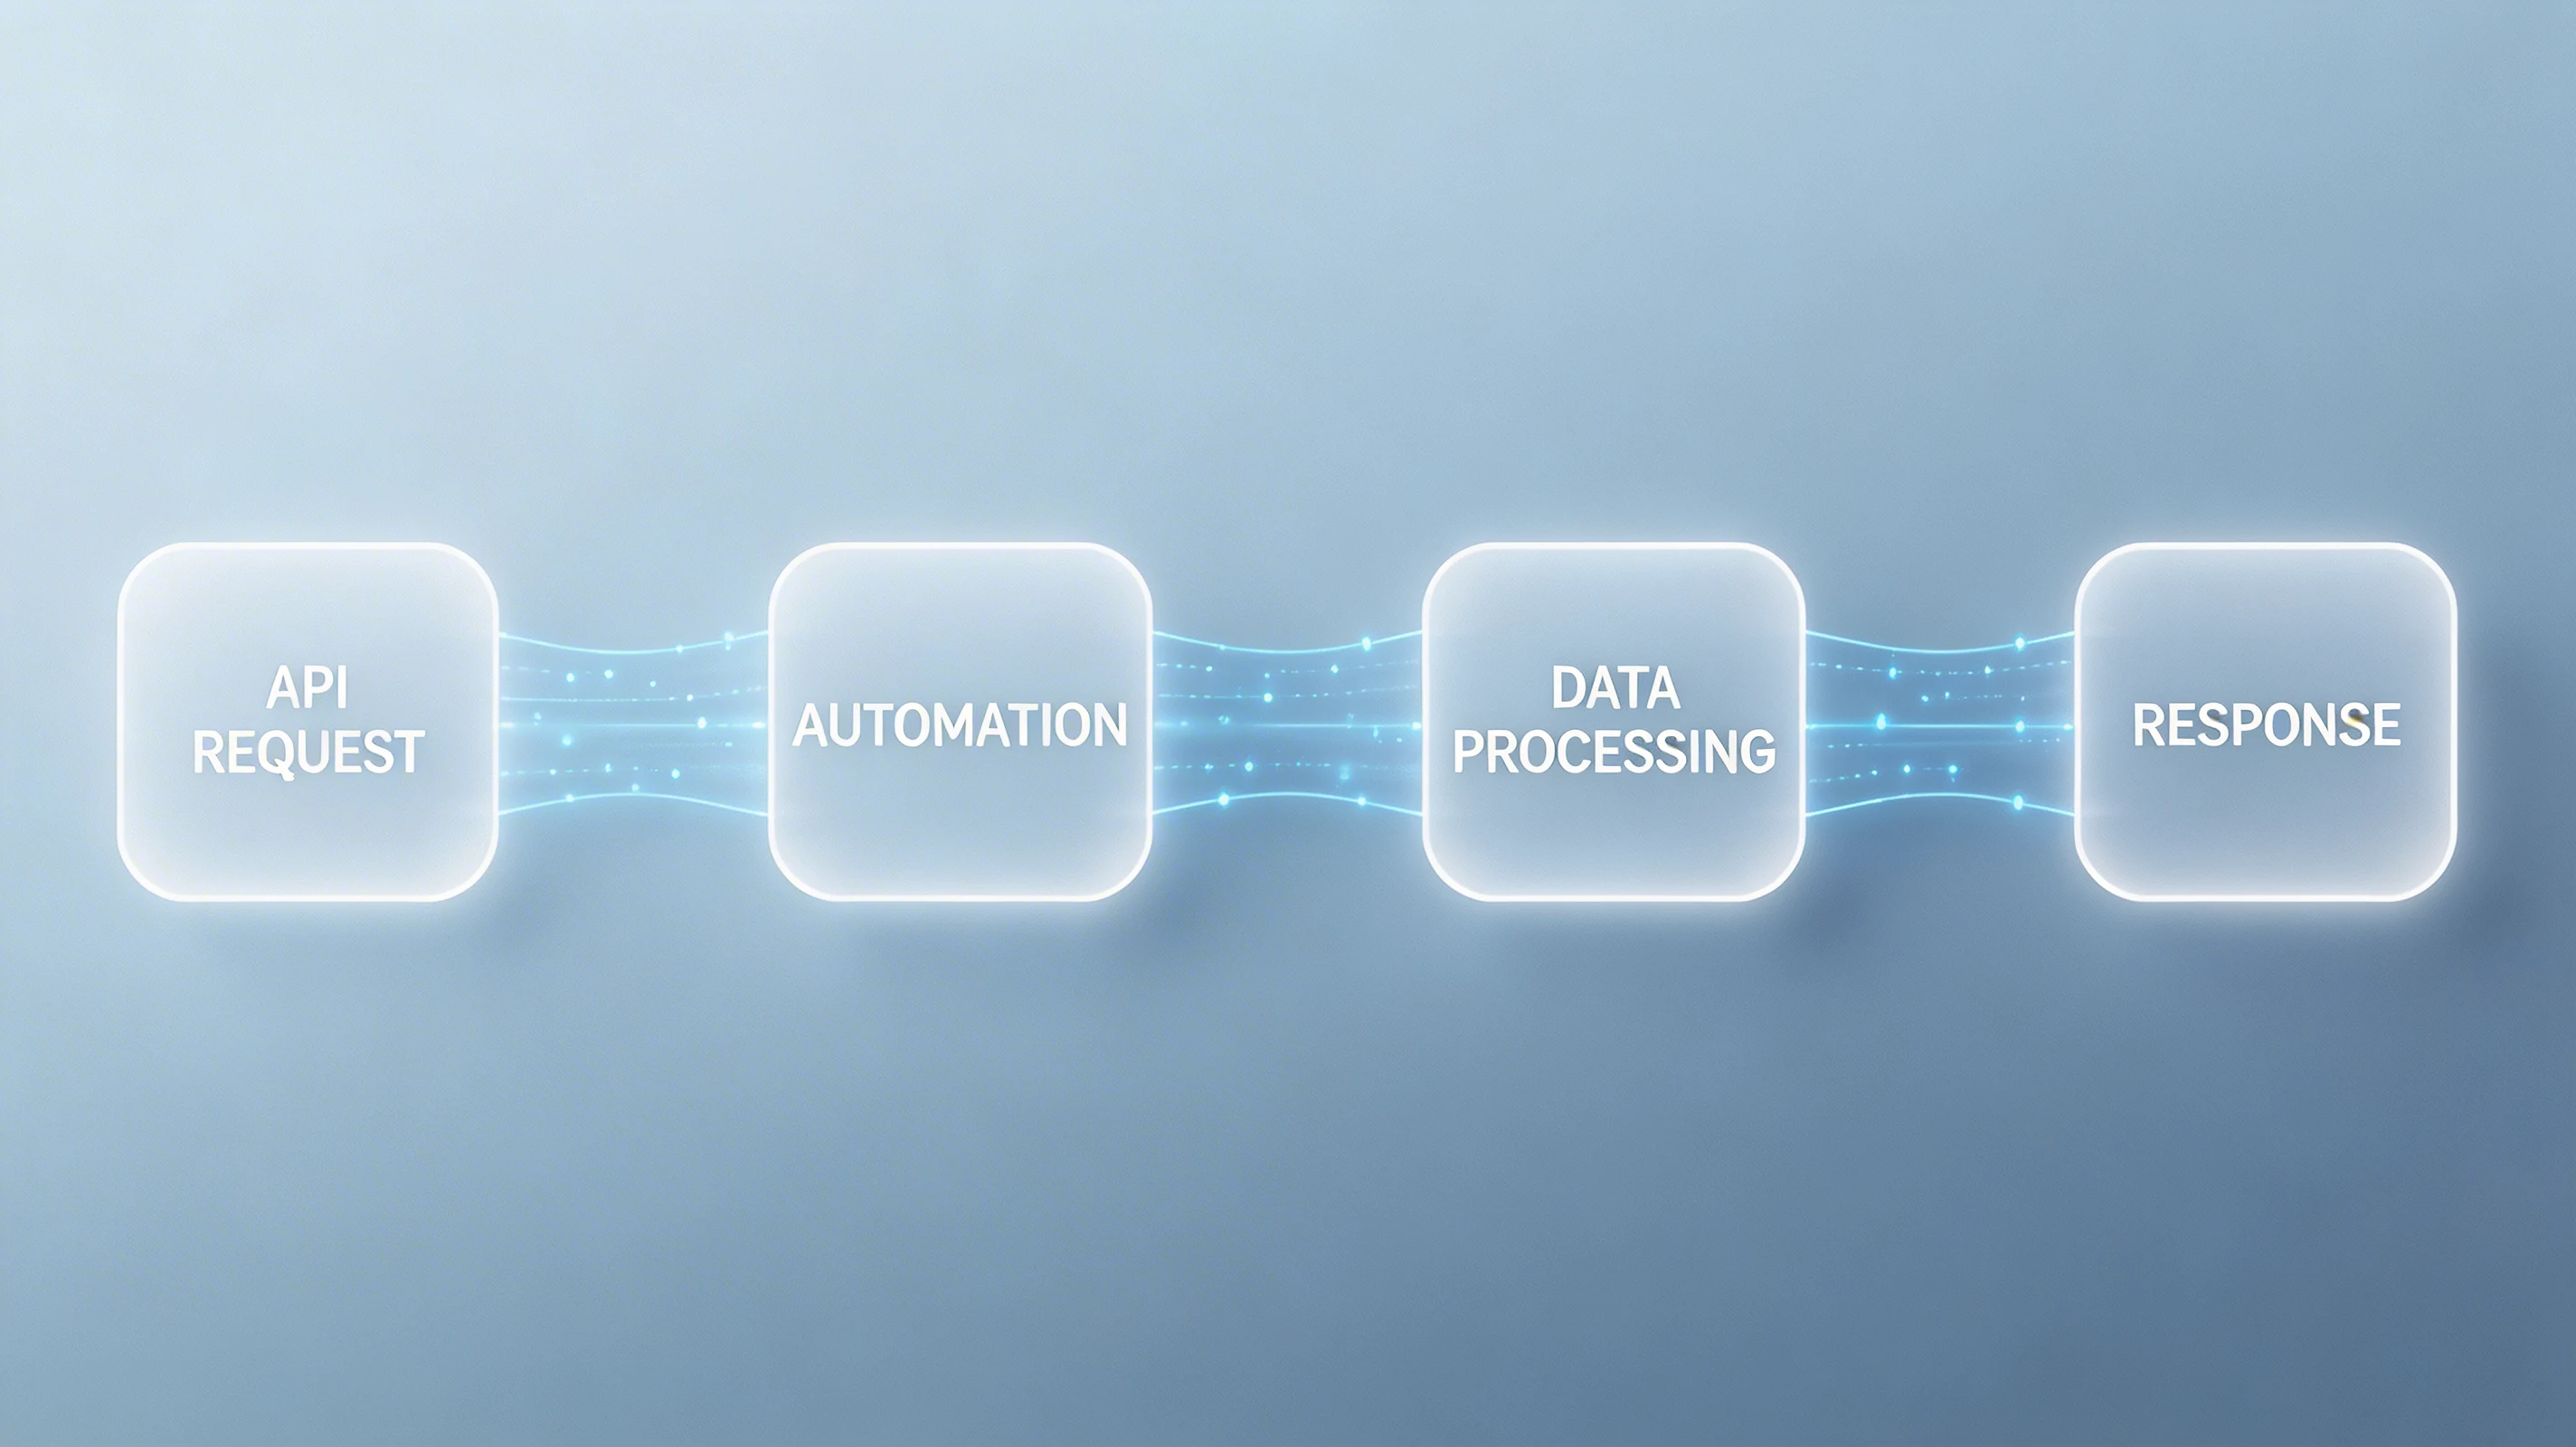
Call MCP tool "generate_dialogue" with provider "gemini-3.8" for automated one and two speaker audio, with the same voices and limits as Audio → Dialogue.
Where scripted dialogue shines
Two hosts, no studio
Turn notes into a back-and-forth. Filler words add natural hesitations between the two speakers, and a rewritten line is one more render away.
The right voice for the job
Pick from the use case that fits, a commercial voiceover, a concierge or a tech support agent, and keep a whole script in one render of up to 5,000 characters.
MCP tool generate_dialogue
Call generate_dialogue with provider 'gemini-3.8', a list of speakers and ordered dialogue turns: the same pipeline as the Dialogue studio.
Gemini 3.8 Flash TTS
Write a two-voice scene with Gemini 3.8 Flash TTS
Open Audio → Dialogue, choose the 3.8 Flash model, and cast your speakers. Credits stay in one wallet with music and video.